Skip to main content Signal blog Official Microsoft Blog Command Line Microsoft On The Issues Asia Canada Europe, Middle East and Africa Latin America The Code of Us What's new AI Innovation Digital Transformation Sustainability Security Work & Life Diversity & Inclusion Unlocked Microsoft 365 Azure Copilot Windows Surface XBOX Deals Small Business Support Windows Apps Outlook OneDrive Microsoft Teams OneNote Microsoft Edge Moving from Skype to Teams Computers Shop XBOX Accessories VR & mixed reality Certified Refurbished Trade-in for cash XBOX Game Pass Ultimate PC Game Pass XBOX games PC games Microsoft AI Microsoft Security Dynamics 365 Microsoft 365 for business Microsoft Power Platform Windows 365 Small Business Digital Sovereignty Azure Microsoft Developer Microsoft Learn Support for AI marketplace apps Microsoft Tech Community Microsoft Marketplace Software companies Visual Studio Microsoft Rewards Free downloads & security Education Gift cards Licensing Unlocked stories View Sitemap

By builders, for builders.

A Microsoft publication

LLM-as-translator pattern: Adding natural language understanding to an existing system without rewriting it

Many companies have legacy systems that still get the job done. But as technology advances, new innovations arise that those companies will want to leverage. 

Take conversational search. With the growing prevalence of LLMs, many consumers now expect the ability to have a natural-language conversation with search capabilities to help them find what theyโ€™re looking for, refining results along the way. However, most retailers already have search capabilities, often keyword-based, that work from existing catalogs. Often, these platforms support the rest of the business by providing APIs, which make them approachable and easy to use. 

The first instinct may be to replace those legacy systems, but modernizing the implementation can be expensive and disruptive to the business. 

One approach is to introduce an abstraction layer that enables a modern faรงade over an existing implementation. Rather than replacing the system, this layer translates the request into something that the system understands. 

While the use case discussed here is a search capability, this approach can be applied to any system that requires structured input.

Core principle

The system already knows how to answer a structured query. But it canโ€™t parse a natural language request like “a cheap red kettleโ€ into the required structured format:

query = "kettle" filters = color:red, price:0-30

Translation between a fuzzy human phrasing and a precise, structured format is exactly the kind of context-sensitive task LLMs are good at. It’s also a boundedโ€ฏtask. The LLM never touches the data, never ranks results, and never decides whatโ€™s correct. It only producesโ€ฏinputโ€ฏfor a system that remains the source of truth. 

That boundary makes the pattern safe. If the translation is wrong, you get a slightly off query, not a corrupted system. And as Iโ€™ll show, you can detect and recover from a bad translation deterministically.

Architecture

The translator is a small service that sits between the caller and the existing implementation.
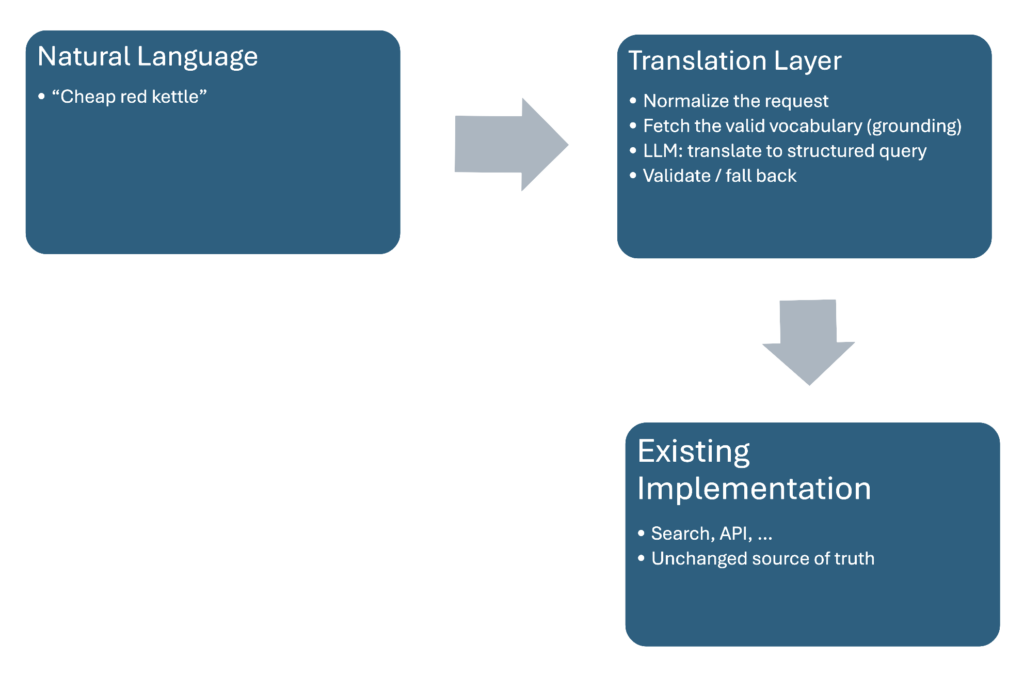
The LLM is never asked to invent structured terms. Instead, itโ€™s given the actual vocabulary the API expects (e.g., valid filters). This eliminates most hallucinations. 

This layer can also downgrade to what the system did before, which means the fallback is baseline behavior.

Pipeline

A translation request flows through four stages.

Stage 0: The shape of the translations

Model the translated query as an explicit type rather than passing loose strings around.

public sealed record StructuredQuery { public required string Entity { get; init; } // the core noun, e.g. "kettle" public IReadOnlyList<Filter> Filters { get; init; } = []; // grounded, validated filters public string? Category { get; init; } // optional classification } public sealed record Filter(string Field, string Value);

Explicit types make validation, caching, observability, and versioning significantly easier than passing loosely structured prompts through the pipeline.

Stage 1: Normalize the request

Strip the modifiers to isolate the core intent and get the entity of interest. This is a lightweight task, so it can be routed to a small, inexpensive model. Keep the prompt narrow with strict output.

public async Task<string> ExtractEntityAsync(string rawQuery, CancellationToken ct) { var messages = new ChatMessage[] { new SystemChatMessage( "Identify the single product the user is searching for. " + "Return only that noun, with no extra words and no attributes " + "such as colour, size, or price."), new UserChatMessage(rawQuery), }; var response = await _cheapModel.CompleteChatAsync(messages, cancellationToken: ct); return response.Value.Content[0].Text.Trim(); }

“a cheap red kettle” โžก๏ธ “kettle”ย 

Stage 2: Ground the model in real vocabulary

This stage is critical, and itโ€™s one that might be missed. Donโ€™t ask the LLM to guess which filters exist. Extract them from the original system and then pass this authoritative list to the model.  

It should be relatively simple to get the vocabulary from most systems. For example, search engines return facets, databases expose their schema, and APIs publish contracts. Once you have the vocabulary, prune it aggressively before sending it to the model. Remove values, nested children, and anything irrelevant. This reduces the number of tokens and can improve latency.

public async Task<string> GetGroundingVocabularyAsync(string entity, CancellationToken ct) { // Ask the engine itself what filters are valid for this entity. var facets = await _engine.GetAvailableFacetsAsync(entity, ct); var json = JObject.Parse(facets); // Prune high-volume, low-signal nodes to keep the prompt small and cheap. foreach (var path in new[] { "$..['values']", "$..['children']", "$..['id']" }) { foreach (var node in json.SelectTokens(path).ToArray()) node.Parent?.Remove(); } return json.ToString(Formatting.None); }

Stage 3: Translate with a strict, grounded prompt

This stage requires reasoning as it maps natural language onto a structured vocabulary. The prompt does three things: states the task, supplies the grounding data, and forbids intervention.

public async Task<IReadOnlyList<Filter>> TranslateFiltersAsync( string rawQuery, string vocabulary, CancellationToken ct) { var messages = new ChatMessage[] { new SystemChatMessage( "Translate the user's request into filters for a search engine. " + "Choose ONLY from the fields and values in the provided vocabulary; " + "do not invent fields or values that are not present. " + "[ SystemChatMessage the user's request"filters\":[{\"field\":\"\",\"value\":\"\"}]}. " + "Vocabulary: " + vocabulary), new UserChatMessage(rawQuery), }; var options = new ChatCompletionOptions { // Constrain the model to valid, parseable output. ResponseFormat = ChatResponseFormat.CreateJsonObjectFormat(), Temperature = 0f, }; var response = await _capableModel.CompleteChatAsync(messages, options, ct); var payload = JsonSerializer.Deserialize<FilterPayload>(response.Value.Content[0].Text); return payload?.Filters ?? []; } private sealed record FilterPayload(IReadOnlyList<Filter> Filters);

Itโ€™s worth highlighting the request for structured output and a Temperature setting of 0 to reduce creativity.  

The independent sub-translations have no dependency, so they can be run concurrently.

var filtersTask = TranslateFiltersAsync(rawQuery, vocabulary, ct); var categoryTask = ClassifyCategoryAsync(entity, ct); await Task.WhenAll(filtersTask, categoryTask); var query = new StructuredQuery { Entity = entity, Filters = await filtersTask, Category = await categoryTask, };

Stage 4: Execute with graceful degradationย 

A successful translation could still be too narrow and return no results. In this use case, that wouldnโ€™t be good. Therefore, begin with the full translated query and progressively relax it, ultimately ending with the untranslated query the system would have run anyway.

public async Task<SearchResult> ExecuteAsync( string rawQuery, StructuredQuery translated, CancellationToken ct) { // Ordered from most specific to the original baseline behaviour. var attempts = new Func<Task<SearchResult>>[] { () => _engine.SearchAsync(translated.Entity,translated.Category,translated.Filters,ct), () => _engine.SearchAsync(translated.Entity,category: null,translated.Filters,ct), () => _engine.SearchAsync(translated.Entity,translated.Category,filters: [],ct), () => _engine.SearchAsync(rawQuery,category: null,filters: [],ct), }; foreach (var attempt in attempts) { var result = await attempt(); if (result.HasHits) return result; } return SearchResult.Empty; }

This cascade makes the pattern operationally safe by providing a fallback to known behavior.

Caching the translation

Requests to the LLM are likely to incur cost and impact latency. In this case, this is the translation and not the search. Introducing a cache can deliver a better experience while reducing both cost and latency.  

The translated query should be cached, keyed by the normalized input, and then sent to the search as normal.

public async Task<StructuredQuery> TranslateAsync(string rawQuery, CancellationToken ct) { var key = Normalise(rawQuery); // lower-case, trim, collapse whitespace if (_cache.TryGetValue<StructuredQuery>(key, out var cached)) return cached!; var translated = await RunPipelineAsync(rawQuery, ct); _cache.Set(key, translated, new MemoryCacheEntryOptions { AbsoluteExpirationRelativeToNow = TimeSpan.FromHours(1), Size = 1, // bound the cache - never let it grow without limit }); return translated; }

Caching the translated query rather than the results ensures that the results are against the latest data.  

When to use this pattern  

Consider using this pattern when: 

  • The existing system delivers business value but requires structured data as input
  • You need a way to introduce natural language input without a rewrite of the original implementation
  • The vocabulary that the system requires is well defined

Do not consider using this pattern when: 

  • The system is unable to answer the questionโ€”the translation stage wonโ€™t deliver this capability
  • The task requires the LLM to reason over the dataโ€”this is better suited to another pattern like retrieval-augmented generation (RAG)
  • The introduced latency negatively impacts the end userโ€™s experience

The takeaway 

Beyond just making an existing system smarter, this pattern makes an existing system easier for people to use. By constraining the LLM to translation rather than decision making, organizations can introduce natural language experiences while retaining the reliability, governance, and business logic of the established systems they already trust.
Designing product simplicity for the AI era

When I returned from maternity leave in March 2026, I felt like I had entered an alternate universe. I rejoined a newly restructured organization, moved to a different team, and was managing a new portfolio of products and people within Azure Developer Services. 

I expected to spend time learning a new product space, but I didnโ€™t expect to spend time relearning what it means to be a designer. 

The teams around me were already using GitHub Copilot and agents in their daily work. Designers on my team were moving beyond making static mockups and clickable prototypes in Figma. Some were contributing directly to production code using VS Code or the GitHub Copilot CLI. The traditional boundary between design and engineering seemed more blurred than ever. 

Even though I had spent portions of my leave experimenting with AI, I was still blown away by how quickly things had changed in such a short period of time.

The same forces that were helping teams execute faster were also making it harder to achieve consistency across surfaces.

As I acclimated to my new surroundings, I found myself asking a lot of obvious questions (my kinder rebrand of โ€œdumbโ€ questions). Designers, engineers, and product teams across Azure Developer Services generously shared context, taught me new tools, and helped me understand how products fit together across CoreAI. As I learned more about individual products, I began to see a broader pattern. The same forces that were helping teams execute faster were also making it harder to achieve consistency across surfaces.

Beyond shared components 

CoreAI is Microsoftโ€™s organization bringing together AI platforms, developer tools, and servicesโ€”including Microsoft Foundry and Azure Developer Servicesโ€”to help developers build and operate AI-powered applications. As this portfolio has grown rapidly to meet the evolving needs of AI-empowered developers, so has the number of offerings outside Azure, including the Microsoft Foundry portal and standalone Azure Developer Services portals. Each product serves a different purpose, but we want customers to experience and use them together as a platform. 

As our teams increasingly built portals, a challenge emerged: 

How do independently built products feel like parts of the same ecosystem? 

Many of these portals were already built using Fluent 2, the latest version of Microsoftโ€™s design system. In fact, it was a requirement for any standalone portal to be built using this framework. That gave teams access to the same accessible, high-quality components and visual foundations. But we realized that even though we were using the same atomic components, our suite of products felt disjointed. 

Even though we were using the same atomic components, our suite of products felt disjointed.

Think of a set of LEGOยฎ bricks. The set can include the same color, size, and shaped pieces. However, if you give three people the same materials and ask them to build a house, theyโ€™ll all end up with something that looks pretty different.

Illustrations by Owen Richard.

The same thing had happened with the portals across CoreAI. Teams used the same buttons, tables, and controls while still creating dramatically different navigation models, page layouts, workflows, detail views, and dashboards. Each decision may make sense locally, but when you zoom out and look at the services as a family, you see many points of differentiation that donโ€™t serve a purpose. In other words, the differences are not earned. This happens when humans are making decisionsโ€”and itโ€™s even more of a problem when agents are at the helm, since they leverage historical choices that might not have been correct in the first place. 

For customers moving between related products, that friction shows up as cognitive overhead. People find themselves repeatedly learning and relearning patterns that essentially solve the same problems. What customers experience as โ€œcomplexityโ€ is often just unnecessary differentiation.

A familiar problem 

Before Microsoft, I spent several years at IBM, where I worked with Carbon, IBMโ€™s enterprise design system. 

In addition to providing a collection of components, Carbon was an organizational strategy for creating coherence across a large and growing portfolio of products built by different teams. At IBM, I saw firsthand how a shared design system helps teams align as products evolve by giving them a common foundation while preserving room to solve distinct customer needs. Without that shared foundation, even reasonable local decisions can accumulate into complexity for customers. 

โ€œInconsistency compounds.โ€
– Dave Chan

 As Foundry Product Designer Dave Chan poignantly observed, โ€œInconsistency compounds.โ€ 

That experience shaped how I understood what I saw across CoreAI. Our teams didnโ€™t lack talented designers, strong engineering practices, or a shared component foundation. Fluent 2 already provided much of that. The challenge was creating coherence across a rapidly expanding ecosystem of products while preserving the flexibility individual teams needed to solve unique customer problems.

AI was changing how the software itself was being built and whoโ€”or whatโ€”was consuming the design system.

In many ways, CoreAI was facing a modern version of a challenge enterprise software organizations have wrestled with for decades. The difference was that, this time, AI was changing how the software itself was being built and whoโ€”or whatโ€”was consuming the design system.

Product simplicity as a strategic priority 

This spring, EVP of CoreAI Jay Parikh introduced product simplicity as a strategic focus area. He challenged us to reduce unnecessary complexity and create experiences that are easier to understand, learn, and trust. 

CVP of CoreAI Design John Maeda has explored this focus area and teased it out into four complementary disciplines. These pillars all contribute to the overarching notion of product simplicity: 

  1. Decision Making: Build the right thing through deep customer understanding.
  2. Engineering Craft: Build and refine resilient, high-quality systems.
  3. Coherence Making: Create consistency across experiences.
  4. Product Craft: Deliver thoughtful, polished experiences customers value.

The challenge we were facing heavily aligned with coherence making. As products evolved independently, how could they still feel connected? Thatโ€™s a question that a traditional design system could solve. More importantly, how could they continue feeling connected as AI accelerated the speed at which software was being created? Thatโ€™s a question for this new era.

Learning from existing success 

Fortunately, we werenโ€™t starting from scratch. Teams working on Microsoft Foundry had already spent significant time solving similar problems. In preparation for its Next Gen release, a group of contributors developed a design system for Foundry, with Senior Designer Owen Richard playing a leading role in shaping its vision for developer audiences.  

This system delivered a smooth, clean, and modernized experience. It was further influenced by Foundryโ€™s sister products, GitHub and Visual Studio Code, so the team crafted components and patterns that felt familiar across these canvases. Functionally, the team leveraged the best parts of Fluent under the hood, so they wouldnโ€™t waste time reinventing the wheel. The result was a curated collection of components forked from Fluent and styled in a design language specific to Foundry. UX Engineer James Bradford refined the production components for this system, ensuring they were accessible to coding agents. In parallel, the UX engineering team also created a prototyping sandbox called Mini Foundry, which empowered designers and PMs to prototype in code while avoiding the complexities of Foundryโ€™s production codebase. 

Through this exercise, Foundry defined variables that emerged through customer feedback, iteration, and the practical realities of building a complex product at scale.

Rather than creating yet another independent design system for Azure-based experiences, we saw an opportunity to build on the Foundry design teamโ€™s extensive work. That is the genesis of the CoreAI Design System: a framework to unify the suite of services under the CoreAI umbrella. 

The goal has never been to make every product identical. Rather, our goal was to establish shared expectations around common experiences. Thereโ€™s no reason why every portal should have a different create flow. People moving between products should encounter familiar approaches to tables, detail pages, navigation models, and other recurring patterns.  

Consistencyโ€”or lack thereofโ€”was the symptom of a problem that simplicity could cure.

Designers and engineers should start from common foundations rather than reinventing solutions repeatedly. Not only does this simplicity improve the customerโ€™s experience, it also saves unnecessary production toil spent reimagining patterns over and over again in each portal experience. 

Consistencyโ€”or lack thereofโ€”was the symptom of a problem that simplicity could cure. 

Product simplicity for humans and agents 

As we worked toward product simplicity, we had to acknowledge that the way software is created has changed drasticallyโ€”and it continues to do so. 

Historically, design systems were built primarily for humans. Designers worked in design tools like Figma and engineers worked in code. Design engineers and frontend developers often bridged the gap, translating design intent into production implementation. 

That model is evolving. Today, designers can describe a change to their Copilot and receive a working implementation. The artifact moving between design and engineering is no longer always a mockup or specification. Increasingly, it is code. 

If product simplicity depends on consistent implementation across products, and AI systems are participating in implementation, then design guidance must be consumable by more than just people. It must be consumable by the agents helping build the experience as well. This understanding influenced how we approached the CoreAI Design System. 

Rather than only creating a traditional component library accompanied by documentation, our goal is to design a system that supports both human decision-making and AI-assisted development workflows. This strategy will support designers at varying stages of their product teamsโ€™ AI readiness.

Illustrations by Owen Richard.

If youโ€™re operating with the clickable prototype handoff, you can use our Figma library as a resource. The CoreAI Figma library is the more traditional repository of guidance and redlined componentry that designers are highly familiar with. 

If youโ€™re making changes in code, youโ€™ll be able to connect to our MCP server. To make this possible, weโ€™re adding a context layerโ€”a set of references and metadata that both humans and agents can use to interpret guidance and adapt it to their specific scenarios. This context layer ensures that recommendations arenโ€™t just static rules but living guidance that adjusts to the needs of different products, teams, and implementation environments. 

Our MCP server provides access to getting started guidance, usage examples, implementation recommendations, and pattern documentation. This is currently experimental, and designers are testing this methodology as I write and as you read. Through this effort, James Bradford and other design engineers made notable revelations. 

  • API documentation proved to be one of the least valuable pieces of information. Agents can often understand component APIs directly from installed packages and TypeScript definitions. What they struggle with is intent. When should a pattern be used? What approach should be used and why? Examples, constraints, and guidance often matter more than API signatures.
  • Progressive disclosure benefits agents just as much as people. Instead of organizing knowledge into large documents, guidance is broken into smaller focused topics connected through references and indexes. This lets agents retrieve only the information relevant to the task at hand, reducing noise and improving implementation quality.

One goal of our system is to reduce the distance between design intent and production code. Instead of treating handoff as a static artifact, we want designers to be able to describe changes, work with AI-assisted tools, and generate experiences built from the same foundations used in production. In that world, the design system becomes less of a reference manual and more of an active source of truth shared by designers, PMs, engineers, and agents. By delivering our system through various mechanisms, we also acknowledge that not all components should be distributed the same way. Some patterns are more appropriately delivered as reusable components. Others work better as template examples that teams can fork to adapt to their own environments. Or maybe a team just needs examples demonstrating preferred approaches to common product scenarios. 

Ultimately, consistency in service of our customers is what product simplicity is all about.

By designing the system around how both people and agents consume information, we increased the likelihood that shared patterns would be applied consistently across products. And ultimately, consistency in service of our customers is what product simplicity is all about.

Building a community around simplicity 

Creating guidance for foundational elements was only part of the work. We needed a model that supported continuous addition and refinement for high-impact patterns. Designers and design engineers from Foundry and Azure Developer Services formed a v-team (James Bradford, Alex Britez, Will Eastler, Dana Lachman, Owen Richard, Kham Udom, and myself) to continue building out pattern guidance that had the highest impact and highest usage across our canvases. 

To ensure our solutions addressed a variety of use cases, we recruited volunteers from multiple product areas for month-long sprints dedicated to formalizing and documenting these patterns. By using product designers to build out our guidance, we ensure they account for realistic scenarios that theyโ€™ve seen in their own products or peer products. The first sprint tackled data grids and detail pages, with Foundry designers Amy Chen, Dasi Fletcher, and Thoa Nguyen leading the effort. Their success set the stage for a second sprint, where Azure Developer Services designers Kristin Holifield and Xiaowei Jiang created templates for a complex but high-impact pattern: create flows. 

To maintain momentum and foster collaboration, we established weekly checkpoints and open office hours. These sessions provide a regular forum for volunteers and other design system users to: 

  • Ask questions about ongoing work or upcoming sprints
  • Share feedback and lessons learned
  • Exchange resources and best practices
  • Surface new pattern needs or challenges

When designers identify a pattern that needs attention, they can submit a ticket to our GitHub board. We triage these requests based on priority for inclusion in future sprints. For smaller contributions that donโ€™t require a full sprint, designers are encouraged to submit ad hoc improvements directly to the system. 

Rather than treating consistency as something imposed by a central team, we see it as a capability developed collectively across the organization. 

While thereโ€™s still much to do, we can celebrate early wins and signs of success. What once could have taken months can now be accomplished in a couple days. When partners have the time to grant repo access and review PRs, Azure portal teams can adopt the baseline npm package for the design system in just a few days. In June 2026, no Azure portals were using the CoreAI Design System. In August, over five have the npm package installed, and that number is increasing as we learn about additional portal offerings. Stay tuned in to see how our portals gain coherence across experiences as they release publicly. The design system in and of itself is growing day by day as we support its expansion with dedicated sprints and ongoing contributions from other designers.

Simplicity as a competitive advantage 

The CoreAI Design System is ultimately not a story about components, documentation, or design tooling. Rather, itโ€™s a story about product simplicity. 

We understood that every unnecessary difference creates friction. Every interaction pattern customers must relearn increases their cognitive load. Every fragmented experience makes a portfolio feel more complicated than complex. 

As AI lowers the barrier of creating new features and capabilities, experience quality becomes an increasingly important differentiator. Customers have more choices than ever before. The products that succeed wonโ€™t simply be the most powerful. Theyโ€™ll be the products people can understand, learn, trust, and use with confidence. 

Product simplicity is how we get there. And increasingly, achieving that simplicity means designing systems that can be understood and optimized not only by people, but also by the agents helping people build the future.

Acknowledgements 

Iโ€™d be remiss not to name the folks who made significant contributions to this work in production, guidance, and leadership: James Bradford, Alex Britez, Will Eastler, Dana Lachman, John Maeda, Owen Richard, and Quirine van Walt Meijer.


All em dashes have been intentionally used by this postโ€™s human author, who currently leads the design team for Azure Developer Services in CoreAI.

Watch TypeScript creator Anders Hejlsberg on The Peterman Pod

How does a team tackle the port of one of the most popular coding languages used every day by millions of developers?

In 2025, TypeScript was the most used language on GitHub, according to the 2025 GitHub Octoverse report. And in July 2026, the TypeScript team released TypeScript 7.0. The new TypeScript is a 10x faster native port designed to streamline the developer experience, with core editor features like auto-completion and diagnostics now taking a fraction of the time they used to. The creator of TypeScript and Microsoft Technical Fellow Anders Hejlsberg recently sat down with host Ryan Peterman to record an episode of The Peterman Pod. They discussed the process of porting from TypeScript to Go, the technical decisions and tradeoffs the team made, and lessons learned along the way. They also talked about Hejlsbergโ€™s approach to creating programming languages, the use of AI to update large codebases, and both the value and limitations of agentic AI today.

Check out the full episode:

From the beginning, TypeScript promised to deliver JavaScript that scales. By incorporating strong type-checking and rich tooling, TypeScript made it possible to build and ship non-trivial, high-quality apps across platforms.

โ€œWe all stand on the shoulders of giants,โ€ acknowledged Hejlsberg. โ€œNo programming language was ever created in perfect isolation, right? Everyone learns from everyone. Someone comes up with a good idea, and then you see it adopted elsewhere. Thatโ€™s how the industry moves forward, really.โ€

โ€œNo programming language was ever created in perfect isolation.โ€
– Anders Hejlsberg

The TypeScript team worked for more than a year on a native port built in Go that could make the most of modern hardware. The port maintained the structure and logic of the original codebase to keep results consistent and compatible between the two compilers. The key difference: TypeScript 7 brings native code speed, shared memory multithreading, and several new optimizations that typically yield increased speeds of between 8x and 12x on full builds.

โ€œThe first decision we made was that we were not going to rewrite,โ€ Hejlsberg said. โ€œWe were going to port because only by porting could we preserve the semantics, algorithms, and exact behavior of our existing compiler, which everyone depends on for backwards compatibility. Now, we could have cleaned the slate and started it completely from scratch, but we would have come up with a different language in the sense that it would give you different errors or behave differently in certain situations.โ€

Next, the team had to decide on a programming language for the port. After looking at some core assumptions made by the TypeScript codebaseโ€”the presence of garbage collection as well as the first-class treatment of functions, for exampleโ€”Go emerged as the clear winner.

โ€œWe tried Rust, and it just wasnโ€™t feasible.โ€
– Anders Hejlsberg

โ€œWe tried Rust, and it just wasnโ€™t feasible,โ€ noted Hejlsberg. โ€œGarbage collection is done manually, or itโ€™s done through the borrow checker, but the borrow checker doesnโ€™t allow circular data structures. And our complier is chock-full of circular data structures. We have trees with parent pointers; we have types that are recursive. I mean, itโ€™s everywhere. We were trying to optimize for doing as little work as possible to get us to the payout. And Go is greatโ€”itโ€™s type-safe and memory-safeโ€”so we got all the benefits for less work by going that route.โ€

While that approach was integral to the port, early testing and community partnerships also helped ensure a high quality bar.

The Visual Studio Code team made an early bet on TypeScript, working closely with the TypeScript team to give developers built-in support for both TypeScript and JavaScript. Recently, VS Code adopted TypeScript 7.0 to speed up their own builds, improve the daily editing loop for agents as well as developers, and ensure that the TypeScript team could ship a more tested release.

Early versions of TypeScript 7.0 were also tested internally at scale by Bloomberg, Canva, Notion, Sentry, Slack, and Vanta, with strong results.

Interestingly, agentic AI didnโ€™t play much of a role in the portโ€”a fact that Hejlsberg chalks up to timing.

โ€œWe started this project two years ago,โ€ he said, โ€œand LLMs were nowhere near as good as they are now. Thatโ€™s how crazy-fast itโ€™s all moved, right?โ€

The team wrote its prototypes, including the scanner and parser, manually. Once convinced that 10x performance gains were possible, they wrote a tool that syntactically translates TypeScript into Go. That gave them code with no syntax errors, but it didnโ€™t properly compile.

โ€œAll of that had to be refactored,โ€ said Hejlsberg. โ€œWe had to redo all the data structures, but we got the same codebase out of it. Then we could sort of bang on that and then, in a more localized fashion, use AI occasionally to help us with the transformation. Now, if we were to start the project today, would we do it differently? Possibly, although I will say that if we just let AI loose on the code in the old compiler and asked it to translate it all, I donโ€™t know if that would absolve us from then having to go in and carefully examine every line that came out of it to make sure there were no hallucinations. Unless you have 100% perfect test coverage, you probably still have to go back and check all of that.โ€

As for working with AI, Hejlsberg called out that LLMs are stochasticโ€”something we should all keep in mind as we determine when and where to deploy these tools.

โ€œSometimes you donโ€™t ask AI for the answer. You ask it for a program that computes the answer.โ€
– Anders Hejlsberg

โ€œThatโ€™s always the thing about AI that people forget: Itโ€™s not deterministic, right? So you canโ€™t really trust that itโ€™ll do the same thing twice. But itโ€™s very good at writing programs, so itโ€™s kind of funny. Sometimes you donโ€™t ask AI for the answer. You ask it for a program that computes the answer.โ€

Now, the team uses AI daily in its work: helping to write tests, move pull requests, and more.

โ€œWhenever an issue is logged, the first thing we do is put Copilot on it and see if it can fix it for us,โ€ Hejlsberg explained.

Read the TypeScript 7.0 announcement post and install it.

From research to reality: An interview with Microsoft VP of Security Research Taesoo Kim

More than 100 billion tokens. Thatโ€™s what Team Atlanta spent using a single OpenAI model during DARPAโ€™s Artificial Intelligence Cyber Challenge (AIxCC)โ€”and they didnโ€™t limit themselves to just that model, so the total number of tokens the team used during the two-year competition was well north of that figure.

AIxCC saw some of the best and brightest minds in cybersecurity designing, testing, and improving new AI systems to identify and patch software vulnerabilities in record time. In keeping with the challengeโ€™s goal of advancing the field of cybersecurity, all seven finalist teams open sourced their projects to benefit researchers anywhere.

But it was Taesoo Kim and other members of Team Atlanta who would join Microsoft to turn that research into enterprise-grade product reality.

We sat down with Kim, now a VP of Security Research at Microsoft and leader of the new Microsoft Security FORGE (Frontier Offensive Research & Generative Exploitation) Labs, as well as a professor at Georgia Tech, to learn how the research concepts Team Atlanta explored during AIxCC went on to inform the Microsoft Security multi-model agentic scanning harness (codename MDASH), the role that MDASH plays in Microsoftโ€™s broader DevSecOps story, and what comes next.

CL Command Line

Letโ€˜s jump right into it. What brought you to Microsoft?

TK Taesoo Kim

Oh, thatโ€™s a great question to start. I joined Microsoft about six months ago. After our team, Team Atlanta, won DARPAโ€˜s AIxCC competition, we thought about which company to join, and Microsoft was one of those companies where we found more opportunity for the future, particularly in the context of finding vulnerabilities, right? Microsoft has a huge assetโ€”not just proprietary software like Windows. They also have a platform like GitHub thatโ€˜s literally one of the worldโ€˜s biggest code repositories that you can get access to. So enabling any technologies in that context would be a huge career achievement for our team.

Myself and several members of the team joined Microsoft together. Our team consists of many of my PhD students at Georgia Tech, as well as former PhD students and professors there. We all joined as a single team and competed for the DARPA Grand Challenge.

CL Command Line

Oh, very cool.

TK Taesoo Kim

Weโ€™re really building a team that enables AI–native vulnerability research at Microsoft. And weโ€™re launching the Microsoft Security FORGE (Frontier Offensive Research & Generative Exploitation) Labs so we can focus more, take advantage of frontier AI models, with the goal of completely automating the process as researchers, so that we can ultimately help advance the work. Weโ€™re really pushing the boundaries of finding and fixing zero-day vulnerabilities.

CL Command Line

Following your PhD in computer science at MIT, you joined Georgia Tech as a professor, and then you branched out to the corporate world with Samsung and now Microsoft. What differences have you come across, working for large corporations compared to working in academia? And are there any similarities that people would find surprising?

TK Taesoo Kim

So I would say 20, 30 years ago, universities were at the frontier. They did the latest research, and then industry was following. But lately, the gap between this frontier research and what industry can do has become extremely slim. For example, at Samsung, I was developing integrated SIM cards, which is one of the operating system layers in Galaxy devices, so that they can host multiple SIM card operations inside the kernel. We took advantage of the latest research, like instead of using C, we used Rust because, at that time, this was state of the art. We brought those technologies together and applied them in the context of industry.

Similarly, with AI, this gap between academia and industry, itโ€™s almost none. Our industry often has incredible resources, more than you can imagine, right? Data, compute power, engineering, the backend. That actually makes us excited about the opportunity. In just six months, we could design the project that weโ€™d like to pursue, conduct the research, make a prototype, and then finally arrive at a production-ready system. Thatโ€™s because of all the support that Microsoft can provide. As long as you do great research, you can convince the people inside, your colleagues. And if they see the opportunity for industry, then theyโ€™ll pour all these resources into the effort so itโ€™s extremely successful.

In terms of finding the proper problem that motivates you, what we call an intellectually challenging problem, weโ€™re never short of those in industry or in academia. But here, weโ€™re ready to tackle them if necessary. And we don’t worry too much about funding. But the problem is whatโ€™s really important.ย 

CL Command Line

Let’s switch gears to talk about MDASH. For those who are unfamiliar, whatโ€˜s the elevator pitch?

TK Taesoo Kim

MDASH is what we call Microsoftโ€™s multi-agent, multi-model vulnerability discovery and remediation agent. Given a huge repository, itโ€™s going to find vulnerabilities and propose fixes. But it can take advantage of multiple models.

Itโ€™s not bound to a particular model like Mythos, so we take advantage of the latest and greatest models all together. Not only that, we have more opportunity for token efficiency because of the way we constructed the system. We have more opportunity to take advantage of certain models in specific ways.

CL Command Line

Right.

TK Taesoo Kim

We can use the right model for the right job. Not only that, one of the key ideas of MDASH is to have a dynamic validation model, or proving stage. So weโ€™re not just finding the vulnerability in a static wayโ€”you can just ask an LLM to find the bugs. We actually validate them through discussions among multiple personas we created. They debate whether itโ€™s a bug or not. And then we also pushed the capability to generate an exploit at the end, so that, when we say thereโ€™s bugs, thereโ€™s proof associated with it, so that the security auditor and developer can verify the existence of the vulnerability by actually reproducing it.

CL Command Line

Thatโ€™s a great segue to my next question. MDASH is orchestrating these 100+ specialized agents that are challenging each other. Tell us more about the decision to have multiple models in the room, so to speak, working together, debating, and validating the โ€whatโ€œ and the โ€severityโ€œ of what they find. And Iโ€™m curious if that was your first approach or if you arrived at it through trial and error.

TK Taesoo Kim

The design behind the 100+ specialized agents is tightly related to our lessons learned when weโ€™re interacting with agents. When youโ€™re working with Copilot or any type of coding agent, you can say, โ€Hey, find bugs.โ€œ And it does find bugs, but it takes a long time. It doesnโ€™t know what type of bugs to look for. It doesnโ€™t know what I want, and it spends a lot of time figuring out what a bug even is, right?

But you can specify what you want in much finer-grained detail and just be very specific about what you want to find. For example, you could say, โ€œHey, given the past vulnerability A, can you find a similar bug?โ€ Thatโ€™s the best way to formulate what you want to achieve out of a single agent, but MDASH has more than 100 specialized agents, and it follows a similar philosophy. Each one of the agents has very specific guidelines. โ€œI donโ€™t care about the rest of the bugs, but I really care about this one particular type of vulnerability.โ€

When you can provide fine-grained controls and scope, it accelerates the performance significantly. But unfortunately, if you combine all of them as a single prompt, it has what we call cognitive load around the work that it has to do.

CL Command Line

Right, right.

TK Taesoo Kim

The model gets distracted, you know? โ€Hey, is that really a bug in terms of other bug contexts?โ€œ Itโ€™s self-debating all that stuff in a way where it couldnโ€™t find the bug in the end. We like to make sure that the scope that each model is working on is well isolated, but at the same time, the models donโ€™t have tons of cognitive load in their context windows so that they can really focus on and deep dive into it.

CL Command Line

Thatโ€™s really cool. And then what did the process of designing MDASH teach you about decomposition? Are there parts of vulnerability discovery that really benefit from that specialization, or are there parts that still require more of a general reasoning model?

TK Taesoo Kim

We still have a general reasoning model behind the scenes as well, which is activated all the time. In fact, more than 50% of the total bugs are caught by that non-specialized model, but these are relatively shallow types of vulnerabilities or one of the weakest points in the code repository. With a specialized agent, youโ€™re looking for a very particular vulnerability that otherwise youโ€™re going to miss it.

Our system is designed in such a way that we can assemble all these results together, so you can just unite all these reports and findings in a way that we can push back or push on to the next stage of validation at the end of the scanning. One nice thing about this is that we provide a system where we can assemble everything, where each modelsโ€™ job is to find as many vulnerabilities as possible, but then we have a nicer system to deduplicate and combine them together in a way that we can enable the rest of the pipeline very seamlessly.

When weโ€™re designing those specializations, we take advantage of the past vulnerabilities and corresponding patches. We study any missing gaps between what we can find with the existing vulnerability as a specialized agent and what type of bugs that we observe in the wild but couldnโ€™t find with the agent. Then we create a research agent so we can extract the specialized agent out of that data. Our system supports this accumulation. You can just add another agent, and our system works fine.

CL Command Line

A lot of AI coding and security demos stop at generating a plausible finding, but MDASH is emphasizing proof of exploitability before it gets to a human. What does โ€proofโ€œ mean in the system, and how did you design the pipeline to avoid mistaking plausible reasoning for a real vulnerability?

TK Taesoo Kim

Most static scanning merely complains about, โ€Hey, thereโ€™s a potential bug in this code snippet.โ€ But unfortunately, it doesnโ€™t necessarily mean that an attacker can reach those locations or that you can formulate the constraint in a way that you can trigger those buggy conditions. So in order to achieve this actual exploitability, we like to solve these two problems: reachability and constraint.

Our proving agent provides an input to the program that resolves the reachability issue and triggers the vulnerability at the end. What I mean by this is that, if thereโ€™s a PDF parser render, then we actually create the PDF document in a way that the PDF viewer crashes because of the input that we created, then craft the PDF file that we created as a proof. By crashing your software, by launching the PDF viewer, you can say, โ€Hey, this bug exists. I donโ€™t know exactly what it is, but because of the fact that the program crashed, I know that indicates the existence of that vulnerability.

CL Command Line

Were there any really challenging or non-obvious architectural decisions that you had to make along the way, or any interesting or difficult tradeoffs that you can talk about?

TK Taesoo Kim

In the validation phase, we came up with the idea of debate. At that time, it was kind of a novel at the end. It was also based on our lessons as security operators. What I mean by this: When we discover a vulnerability, when we say thereโ€™s a bug, we create a bug report and show it to the developer. The very first response from the developer is often, โ€Hey, thatโ€™s probably not a bug. Thatโ€˜s the intended behavior because I documented it.โ€œ Even though the program crashed, they documented it, right? This is common behavior. So we created an agent that mimics the behavior of a software developer. It can be defensive.

CL Command Line

Right.

TK Taesoo Kim

So that agent defends against the argument that, according to the design, this is a bug. It might say that the other agent made a mistake and didnโ€™t use it in the right way. But at the same time, another agent takes the offensive perspective, the offensive research perspective. It tries to convince them, โ€œThis is still worth fixing because it has a security implication.โ€

So we created a persona that represents the perspective of the exploit writer and another that represents the perspective of the software developer, and we make sure that they reach a consensus at the end, so that weโ€™re validating certain findings that we have. Either all of the personas that we create reach the consensus, or they feel less severe, less confident about the bug.

CL Command Line

So when agents disagree, thereโ€™s like a voting mechanism that takes place and itโ€™s sort of majority rules. Is that right?

TK Taesoo Kim

Yup. Exactly. So at least we can say this is debatable, but weโ€™re not super confident. We can then mark the finding as less confident, so the rest of the pipeline spends more energy to validate those findings after the validation phase.

CL Command Line

If you were explaining the architecture to other security researchers, where do traditional program analysis techniques still matter the most? And where do you see LLMs or agentic reasoning really changing the game?

TK Taesoo Kim

Many of the traditional techniques, like analyzing core graph, like CodeKL tools, they understand that some of the data flow in program analysis perspective. Whenever we can take advantage of them, we have to because itโ€™s much faster. In order to resolve the core graph, LLMs consume every single piece of source code and analyze it. Itโ€™s extremely expensive, but traditional tools are extremely fast and cheap. So whenever possible, we have to take advantage of them, including core graph generations and data flows and stuff. We provide them as a database and tool in a way that the agent can decide whether we need those analyses separately from the LLM itself.

CL Command Line

Are there any classes of bugs or environments that are still really difficult for agentic systems today? And if so, what would need to change for AI systems to handle them well?

TK Taesoo Kim

There are many types still. For example, side channel is one thing because they have to reason about potential performance characteristics and the codebaseโ€™s actual implementation. This is a very difficult area. Another one, I would say spec-driven vulnerability is a logical error, but tightly bound to the certain spec. For example, if you didnโ€™t correctly implement the spec, thereโ€™s a potential vulnerability there. The LLM has to reason all these together. Theyโ€™re not really good at it because the spec itself is extremely formal.

LLMs are designed to be less formal and handle this, I would say, unstructured input, unstructured code as your input, but you have to juggle between this very formal wording and unstructured wording at the same time.

CL Command Line

Jumping around a bit, how do you see MDASH fitting into todayโ€™s broader Project Perception announcement? Is it one layer of a larger system? How does it relate to the overarching vision for cybersecurity in the agentic AI era here at Microsoft?

TK Taesoo Kim

MDASH can be plugged in at a very early phase of Project Perception, meaning that we identify potential vulnerabilities in the repository, and then Project Perception can take advantage of this information. So if MDASH says, โ€Hey, thereโ€™s a potential bug in here because we know those from the code repository,โ€ Project Perception makes sure that it actually exists in the actual environment that they deploy in and understand the whole network topologies. It has multiple sources of information that theyโ€™re taking advantage of, and MDASHโ€˜s information is one of the very high-confidence, high-fidelity signals to Project Perception.

CL Command Line

And how, if at all, did the insights generated by your work on MDASH help inform the development and training of MAI–Cyber–1-Flash, which is Microsoftโ€™s first cybersecurity specialized model?

TK Taesoo Kim

Weโ€™re closely collaborating with the Microsoft AI team in terms of how to construct the reinforcement learning environment. And also we provided the datasetโ€”this is the past scanning information from internal projects. We discussed how to best utilize a cyber model in a way that can reduce certain inefficiencies in certain bases of MDASH so that we can take advantage of Microsoftโ€˜s internal model as well.

CL Command Line

And then Iโ€˜m just curious, from a broader perspective, how would you characterize Microsoftโ€™s DevSecOps story and vision, and how do you see your work fitting into that larger puzzle?

TK Taesoo Kim

MDASH started as an internal project, so we designed everything for our internal developers. We tightly integrated together with the Copilot SDK so that all the full-time employees at Microsoft can launch MDASH as a project on their laptops. Itโ€™s great, and the Windows developers realized that when they tried to scan their codebases in MDASH, they significantly increased the pace at which they discovered vulnerabilities with high fidelity. And then they really saw the potential of MDASH and started integrating it in the CI/CD pipeline. Weโ€™re also using ADO, Azure Development Ops, inside of most of the projects at Microsoft. So weโ€˜re exhaustively scanning ecosystems and infrastructures across Microsoft by using MDASH. In other words, for certain releases, very frequently, weโ€˜re enabling an MDASH-like scanning tool so that developers can get automated pen testings out of their repository before releasing the software.

CL Command Line

Whatโ€™s next for you? Are there any interesting research questions that youโ€™re exploring at the moment?

TK Taesoo Kim

Weโ€™re focusing on how to automate exploit generations given a finding, which should stop whenever we prove the existence of a vulnerability. But the existence of a vulnerability is different from its exploitation, meaning, whatโ€˜s the implication of this bug? Can we actually take control of the program, and what are the impacts after? Thereโ€˜s a huge difference between, โ€Hey, I can trigger this vulnerabilityโ€ and the program actually crashing. So weโ€™re enabling the last milestone. This is very, very important in the journey of fully automated remediation.

What I mean by this: We discovered the vulnerability, estimated the severity by creating the exploitation, and by using this, we can actually test the generated patch and prevent those exploitations. This is one of the very objective metrics in terms of measuring the validity of the patch that weโ€™re generating. So end-to-end, from discovery all the way down to the exploit generations, and by using it, we like to enable the pipeline for automated remediations as well. This is one of the big journeys that weโ€™re taking.

Another big area is what we call binary support. Certain programs, like many Windows device drivers, donโ€™t have symbols, like even source code. Given that, can you enable MDASH-like systems in those contexts for a broader set of programs, beyond a repository?

CL Command Line

Interesting. If a PhD student or a security engineer wanted to push this field forward, what open research problems would you point them toward?

TK Taesoo Kim

I think one interesting areaโ€”Iโ€˜ve pitched this idea many times to my studentsโ€”is that, in the software world, thereโ€™s a technique called obfuscation. In order to prevent an attacker from analyzing my software, I obfuscate the binary, obfuscate the source code. Many agentic systems minimize their source code, right? They create a bundle. And AI systems are extremely good at unpacking those and understanding them, but what is the technique to influence the analysis that an LLM can perform?

For example, instead of creating just a minimized version, should I introduce a more complex control flow, or is there a technique that we can play with the symbol name in such a way that the LLM can confuse you about the existence of the source code? I think these are pretty interesting new areas of how to defend my software from an LLM power attacker in terms of software analysis. Is there any technique that can slow down that analysis so that we can enable that packaging before releasing my software with an additional layer of mitigation?

CL Command Line

Going back to the beginning and being part of the winning team for DARPAโ€˜s AIxCC competition: Tell me a little bit more about what that experience was like.

TK Taesoo Kim

A DARPA Grand Challenge is one of the biggest competitions in your careerโ€”not just me, but for any computer science professor or researcher. DARPA only announces them very occasionally, maybe every 10 years? Itโ€™s a huge opportunity.

When they announced the AI Cyber Challenge, thatโ€™s my area that Iโ€™ve been working on my whole lifetime. So my clear goal was to demonstrate that we are the best. We are very competitive people. And weโ€™re not just doing this competition. Weโ€™ve won multiple other competitions, but we thought, โ€œWeโ€™re not gonna win this competition.โ€œ People around the world brought their best knowledge and best effort to compete. That was an amazing experience. I never thought of working that hard over two years in my entire career.

CL Command Line

Thatโ€™s pretty amazing. So how did your work in that competition ultimately inspire or inform MDASH?

TK Taesoo Kim

Every single activity that weโ€˜ve done at Microsoft was influenced by AIxCC, even like at the idea level and lessons level. Because after spending 100 billion tokens during the competitionโ€”actually more. So on one OpenAI model alone, we spent more than 100 billion tokens.

CL Command Line

Wow.

TK Taesoo Kim

And we had all these lessons that we had learned. So that was a pretty interesting exercise after the competition. Now we have a huge amount of engineering resources, so letโ€™s tackle this domain of the problem with the insights that we have.

CL Command Line

Right.

TK Taesoo Kim

And thatโ€™s why itโ€™s worked very well in practice.

CL Command Line

Thatโ€™s a crazy stat. I know we’ve covered a lot of ground. But if people reading this story take one thing away from it, what do you hope that would be and why?

TK Taesoo Kim

The world has already changed because of highly intelligent models. Say youโ€™re a software developer or a software company. I think this is a very important moment to think about what an AI power attacker could do to your organization. Itโ€™s just scary at first, but if you think through whatโ€™s going to happen in the longer-term future, this is the first time where the defender might win this game.

Because before releasing new software, we have a huge chance of finding and eliminating all these possible vulnerabilities ahead of time. Iโ€˜m one of the true believers that an MDASH-like system can help us eliminate all of them so that we can win the game. And this is the first time in my career in security where itโ€™s actually possibleโ€”or even probableโ€”that the attacker might lose the game in the end.


Learn more about codename MDASH: 

Learn more about Project Perception: 

Watch Satya Nadella on a No Priors x Latent Space crossover special

After wrapping up the keynote at Build, Microsoft Chairman & CEO Satya Nadella sat down with swyx, Sarah Guo, and Elad Gil for a special crossover episode of No Priors and Latent Space. The conversation covered what it means to build a frontier ecosystem, including the need for a unified and continuously improving agent platform, the value of long-running โ€œautopilotsโ€ like Scout, and Microsoft AIโ€™s ambition to give every business its own โ€œhill climbing machine.โ€ Check out the full podcast episode:

Five ways weโ€™re confusing AI capability and AI realityโ€”and how to bridge the gap

On the evening of June 1 at San Franciscoโ€™s Bartlett Hall, Microsoft CTO Kevin Scott spoke at a joint event with Lectures on Tap, attended by approximately 150 developers, founders, media, and tech industry leaders. His talk focused on what he described as the growing perceptual disconnect between AI capability and AI reality: the tendency to mistake rapid advances in model performance for equally rapid progress in deployment, organizational transformation, trust, and real-world value creation. 

Scott argued that the AI industry is at an inflection point where technical breakthroughs are arriving faster than institutions, workflows, and human systems can absorb them. While acknowledging the extraordinary pace of progress in areas like software development and agentic systems, he emphasized that the difficult challenge ahead is operationalizing these capabilities responsibly and meaningfully at scale. 

Here are his five observations of the ways in which AI reality is diverging from apparent capability. 

1. Capability โ‰  deployment 

According to Scott, one of the biggest mistakes people are making right now is confusing technical capability with real-world deployment. The fact that a model can do something impressive doesnโ€™t mean the surrounding systems, economics, governance, and human behaviors are ready to absorb it at scale. 

We just shouldnโ€™t have uniform faith that, as AI model capabilities improve, weโ€™re going to get this crazy fast deployment everywhere.

โ€œTodayโ€™s AI models are actually more capable than the things weโ€™re using them for in the real world,โ€ he said, addressing todayโ€™s โ€œcapability overhang,โ€ as he has dubbed it. โ€œWe just shouldnโ€™t have uniform faith that, as AI model capabilities improve, weโ€™re going to get this crazy fast deployment everywhere.โ€ 

2. Closed feedback loops โ‰  universal progress 

Scott explained that some areas of AI (like agentic software development) are improving extraordinarily quickly because tight feedback loops allow those systems to iterate, evaluate, and refine outputs at high speed. But that dynamic doesnโ€™t automatically extend to domains constrained by physical systems, regulation, or long experimental cycles.

Tight feedback loops donโ€™t automatically extend to domains constrained by physical systems.

โ€œOne of the things models can already do is postulate new ideas for particle physics experiments,โ€ he said. โ€œAnd the problem with particle physics experiments is that they take a lot of expert technical labor to set up and run, and they require the use of extremely expensive infrastructure. So there really isnโ€™t a convenient wayโ€”other than publications in the scientific literatureโ€”to get the output of those experiments and feed it back into an actual model.โ€ 

3. Software velocity โ‰  organizational velocity 

AI is dramatically accelerating software development production, but that doesnโ€™t mean organizations can suddenly move faster. In many cases, speeding up code generation simply exposes the slower-moving bottlenecks that were already present: deployment, integration, governance, and organizational change. 

โ€œI build a lot of prototypes that are greenfield, where I have no constraints whatsoever,โ€ noted Scott. โ€œI just get an idea and thereโ€™s nothing stopping me from using an agentic coding system to produce a brand-new thing. But in many cases, the things we want to produce are fairly highly constrained.โ€ 

When things are moving this fast, itโ€™s hard for people to notice the change and snap to.

Scott pointed to last-mile problems, the need for a lot of plumbing work, and human psychology as throttling issues. He also acknowledged the forecasting problem we will inevitably face as things move exponentially faster: โ€œA lot of the stuff Iโ€™m doing right now using agentic coding to build things wasnโ€™t even possible in November of last year,โ€ he said. โ€œWhen things are moving this fast, itโ€™s hard for people to notice the change and snap to.โ€ 

4. Activity โ‰  value 

โ€œJust because youโ€™re using AI to create a lot of activity doesnโ€™t necessarily mean that the activity youโ€™re creating is valuable,โ€ Scott said. 

The ability to generate enormous amounts of output doesnโ€™t guarantee meaningful impact. As AI lowers the cost of creation, the defining question shifts from, โ€œHow much can we produce?โ€ to: โ€œWhat is actually worth building?โ€

We have to pay close attention to how we measure value.

โ€œWe can have a lot of output, we can build more complex things than we built before,โ€ added Scott. โ€œThat doesnโ€™t necessarily mean that the things weโ€™re building are super valuable. When they go into a userโ€™s hand, are they solving a real problem? As developers, we have to pay especially close attention to how we measure value and to the feedback we get on the work that weโ€™re doing.โ€ 

5. Autonomy โ‰  trust 

AI systems are becoming increasingly capable of operating autonomously, but autonomy alone does not create trust. Real-world deployment still requires governance, identity, access control, transparency, and meaningful human oversight. 

Thatโ€™s a new way of thinking about software.

โ€œYouโ€™re always going to have human oversight, so this notion of autonomy is a little bit of a pipe dream,โ€ Scott noted. โ€œYou have to build systems doing complex things in a way where people can trust that theyโ€™re doing them correctly and in a way thatโ€™s aligned with their interests and values. And thatโ€™s a new way of thinking about software.โ€ 

Bridging the gap between capability and reality 

Ultimately, said Scott, โ€œThereโ€™s a lot of work for all of us to do over the next months and years to fully unlock the potential of this crazy tool that weโ€™ve built collectively. These problems that I enumerated donโ€™t go away just as a function of scaling up an AI model. There is no silver bullet. That means thereโ€™s a bunch of technical work to be done, a bunch of societal work, a bunch of organizational work, and just dealing with legacy systems and plumbing.โ€ 

AI capability gains will continue, but turning those gains into trusted systems that create meaningful, durable value is the harder and more important work. And that work starts today. 

โ€œWe need to engage more intensely than ever before,โ€ said Scott, โ€œbecause we can see the promise of this technology to benefit the world if weโ€™re able to overcome these obstacles.โ€ 

Introducing Command Line, and the new rules for builders

Welcome to Command Line, a new blog where weโ€™ll share what Microsoft builds, how our technical teams operate, and what we learn along the way. Build 2026 felt like the right time to roll this out, as we bring together engineering leaders from around the world to dive deep on building, deploying, and operating scalable AI systems. For those on the ground in San Francisco, youโ€™ll notice that the vibe has shifted along with the locale. And that seems only fitting since the entire SDLC has changed dramatically, too. 

To kick things off officially on Command Line, I thought Iโ€™d share some of the things weโ€™ve learned about building in the agentic AI era. Things are evolving quickly, and the old rules no longer apply. Manual review processes are breaking under a flood of PRs that our workflows werenโ€™t designed to accommodate. Build time iteration is being met with runtime learning loops as agents improve post-deployment. And the focus is shifting from shipping code to orchestrating systems. 

Things are evolving quickly, and the old rules no longer apply.

This is more than a productivity boost. Itโ€™s an entirely different relationship with code, tools, and decision-making. Throw out the old playbook. We need to develop a new set of rules for builders. 

Here are 10 things that feel important and true today. Time will tell how durable they prove to be. Weโ€™re in a time of seismic disruption, so we all need to constantly challenge our assumptions.  

1. Build agent-first by default 

As you develop your proficiency with AI tools, youโ€™ll probably find yourself reaching for the Copilot CLI in GitHub or agent mode in VS Code more often than not. Many senior engineers on our own teams and across the industry no longer write code by hand, and even small tweaks are made via agents when itโ€™s more efficient. 

2. Context and skills are your most important asset 

When you first start using an agent in your repo, youโ€™ll notice long sessions with higher failure rates. Start by prompting the agent to populate the knowledge base of Markdown files about your repo, verify the output to ensure correctness, and then set up a continuous improvement agent so that knowledge base memory is updated after each agent session. Things start to compound rapidly. 

If youโ€™re doing something repeatedly with an agent, wrap it into a reusable skill and share it. Team skills compound the same way code libraries do. If the same agent failure shows up twice, promote the correction into a reusable skill, test, eval, prompt, or workflow with a clear trigger. 

3. Plans are the real work 

When you invest in a good plan, the agent can often one-shot the implementation. Shift your energy from typing out code to shaping clear, scoped roadmaps. Human judgment lives in the plan. Execution runs on autopilot. 

4. Prototypes replace detailed PRDs 

Learning by doing should become the default. Experiment with live demos and prototypes to establish ground truth and guide your decisions before you commit to building. Think demos, not memos. 

5. Taste, not time, is the crucial limited resource 

When building is cheap, the discipline of deciding whatโ€™s worth building becomes more critical, not less. Product judgment and prioritization are the highest-leverage skills on the team. Additionally, with near-zero cost to prototype, deciding what to build now includes seeing concrete options upfront. 

6. Tackle the important but overlooked 

AI-forward velocity reclaims bandwidth for critical, high-value engineering debt and operational tasks that usually get pushed aside.โ€ฏThat includes finding and fixing high-value sentry errors, repairing broken telemetry dashboards, running sentiment analysis on dogfooding feedback, and operationalizing more rigor in your data quality. 

7. Tests are your safety net 

At high velocity, good test coverage is what prevents you from shipping regressions. Invest in test quality the same way you invest in feature velocity. 

8. Donโ€™t let code review become a bottleneck 

When small teams can ship hundreds of PRs every month, staying close to the codebase requires deliberate effort. Start using and trusting agentic code review tools like CCR, shifting first-pass code reviews to agents, and keeping humans in the loop for architectural oversight. 

9. Everythingโ€™s changing, not just code 

Build pipelines, verification, triage, planning, and team rituals all need to evolve. Longer shipping cycles gave you more time to uncover bugs. Shorter shipping cycles and a higher pace of code turnover decrease that buffer. As AI-assisted PR volume increases, you need automated, fast quality gates to keep up. 

10. Code is disposable 

Donโ€™t be afraid to throw code away or rewrite it. For well-bounded features, the spec might become the durable artifact. And because code is disposable, you can be brutally honest in review and ditch what doesnโ€™t serve the product. Embrace an egoless culture. 

Taste should be the sharpest tool in your arsenal.

Bonus: Another word on taste 

In the agentic AI era, taste is the ultimate differentiator and should be the sharpest tool in your arsenal. But donโ€™t just set it and forget it. Keep coming back and feeding the flywheel. Human taste can be captured once in curated examples, then enforced continuously across every agent trajectory. The compounding improvement loop means that as you give feedback, the bar keeps rising. 

Thatโ€™s how you get high-quality code without humans writing every line. 

Microsoft Scout: From personal project to enterprise-ready personal agent

Early this year, OpenClaw demos were seemingly everywhere, though many seemed to amount at best to a cool party trick (โ€œLook, my agent ordered a pizzaโ€). But it got long-time Microsoft employee Omar Shahine thinking: How useful could claws actually be? 

Very, it turned out. In his spare time, Shahine created Lobster, a personal AI assistant built on OpenClaw. It has its own Apple ID and email address, so he can text with it from any device with iMessage. He initially split Lobster into a trio of agents, each with its own security profile and tool access (eight weeks in, that number had increased to nine always-on agents). Lobster handles travel logistics, proactively sends family reminders ahead of time, and generally helps Shahine and his family stay organized and get things done. And after presenting Lobster to Microsoftโ€™s AI Accelerator group, it landed Shahine a new job: bringing OpenClaw to M365 and the cloud as CVP of what was deemed โ€œProject Lobster.โ€ 

At the same time, Microsoft Member of Technical Staff Jakob Werner was pursuing a similar idea with a twist: a desktop app-based agent inspired by OpenClaw. The goal was to deliver a powerful enterprise-secure personal AI assistant that anyone within Microsoft could use. In just a couple weeks, what was referred to internally as โ€œClawpilotโ€ had already been downloaded by thousands of Microsoft employees, and that community continues to grow. 

When Shahine started assembling a small team of enthusiastic buildersโ€”Oceanโ€™s 11, naturallyโ€”Werner quickly joined their ranks. The two recently caught up in Redmond, Washington, to compare notes on building these always-on, autonomous agents and navigating the worlds of enterprise security, agentic memory, and more.

Embracing the spirit of open source 

The Project Lobster team is representative of a new way of working within Microsoft, fueled by AI advancements. Itโ€™s a tight-knit group that prefers to collaborate asynchronously. Thereโ€™s a general consensus against meetings. Everyone contributes to the codebase, including Shahine. And thereโ€™s no traditional executive assistant among their ranks: Each team member actively uses prototypes throughout the day to fully immerse themselves in the tech as theyโ€™re building it. Thereโ€™s even a growing open-source community around the team that mirrors whatโ€™s found with open-source projects outside Microsoftโ€™s walls. 

โ€œIโ€™ve never seen a project inside the company where so many people showed up with their ideas and their code and did the work to produce a PR,โ€ says Shahine. 

Iโ€™ve never seen a project inside the company where so many people showed up with their ideas.

In fact, internal excitement around Project Lobster has been such that the team fielded pull requests (PRs) left and right during the early building phase, which they reviewed to determine whether they met the bar to make it into the product. Even some of Shahineโ€™s changes didnโ€™t make the cut. The focus had to remain on the central goal of the product: Creating an always-on personal agent for work. An AI helper that learns your goals, adapts to your daily work patterns, and acts with context, identifying issues before they surface, keeping projects on track and driving outcomes without constant input. An agent that can detect when a calendar is overbooked and propose specific changes before the week begins or identify when a decision is stalled and draft a targeted follow-up to unblock it. 

โ€œWe have to determine if a given PR changes the central idea of the product or notโ€”and the speed of that review is human speed, not AI speed,โ€ notes Werner. โ€œAnyone can make a PR super quickly now. Weโ€™re trying to help the community and teach contributors how to review PRs.โ€ 

While the work began as an internal experiment, it quickly turned into a customer-focused effort thatโ€™s culminated with the introduction of Microsoft Scoutโ€”an always-on personal agent powered by OpenClaw open-source technology. 

From experiment to enterprise-ready product 

Microsoft Scout operates autonomouslyโ€”with its own identityโ€”acting on your behalf. It works across cloud, desktop, and web browser, so it can connect across the surfaces you useโ€”Teams, Outlook, OneDrive, and SharePointโ€”and the systems where work lives, including email, calendar, and contacts. 

Unlike your average claw in the wild, Microsoft Scout combines OpenClaw code with enterprise identity, governance, and security. Every package is ingested through a curated, signed Microsoft supply chain, and every tool call, model request, and network hop is mediated by a zero-trust runtimeโ€”the agentโ€™s container is treated as untrusted, with Microsoft-controlled identity, tokens, and policy sitting outside it. With Agent 365, admins get a single control plane, and Microsoft Purview gives security teams the same compliance and DLP signal they already get from other M365 surfaces. 

โ€œItโ€™s a super powerful tool,โ€ acknowledges Werner. โ€œAnd to be enterprise secure, we needed to make sure the data governance was right, that the privacy was right, and that it doesnโ€™t cancel a meeting and send all your personal information to that email chain. If I send my agent to you, it shouldnโ€™t tell you everything about me. These areas are possible to contain, but we also had to do it in a balanced way that doesnโ€™t restrict the possibilities down to nothing.โ€ 

Itโ€™s a tradeoff worth making. And with Microsoftโ€™s tried and trusted enterprise security offerings and ongoing research and innovation in the space, the team had a solid foundation from which to address the challenge. 

The role of agentic memory 

In order for an always-on personal AI agent to be truly useful, it needs to be proactiveโ€”and that requires context powered by Work IQ. Over time, Microsoft Scout understands the way you work, uses the same productivity tools you use, and takes things off your plate without the need for constant prompts. It learns your goals, adapts to your daily work patterns, and acts with intent. Unlike previous technological waves, this is software thatโ€™s truly personalized. Thatโ€™s transformative, but itโ€™s not without tradeoffs. 

โ€œOpenClaw, Claude Code, GitHub Copilot CLI, these are agentic coding harnesses that are basically rememberingโ€”writing things down just like people do,โ€ Shahine notes. โ€œThey write things down like a diary. But just like it needs to remember things, it needs to forget some things, too.โ€ 

Just like it needs to remember things, it needs to forget some things, too.

As an example, Shahine points back to the introduction of memory to ChatGPT. He spent some time telling ChatGPT that his daughter was 17 while his son was 13. But a year later, that information remained static. The system didnโ€™t have a concept that some facts need to change over time, while other pieces of informationโ€”like your nameโ€”will stay exactly the same. 

โ€œIn the design phase, I was thinking about the human and how humans memorize things,โ€ says Werner. โ€œI forget things that are irrelevant because I didnโ€™t use them. So I built a system where, if Iโ€™m going to use it repeatedly, itโ€™s going to stick. But if Iโ€™m not going to use it regularly, I want the system to forget. I donโ€™t want to have an infinite diary of things, right? So thereโ€™s kind of layers of memory, and it kind of disappears over time if itโ€™s not used. Meanwhile, the relevance of other pieces of memory grows as you use them more.โ€ 

Forming a new center of gravity 

When they first joined forces, Werner introduced Shahine to the concept of gravityโ€”the framework around which he operated. 

โ€œTo build a truly great product, I donโ€™t think I can make it myself,โ€ Werner explains. โ€œWe need to collaborate with other people. But how do we influence other people to collaborate with us? And the mindset I use and try to instill in my team is gravity. We build something and make it so big in influenceโ€”not in the number of features, but in its influenceโ€”that when exciting new ideas pop up, they want to try and join the gravity of our work rather than dissolve focus.โ€ 

โ€œAnd I didn’t really know what you were talking about until my new role was announced,” admits Shahine. โ€œBut since then, Iโ€™ve received hundreds if not thousands of messages from people who want to help, people who want to learn, people who want to show me what they did, and customers who want to know ASAP when theyโ€™re going to get their hands on what weโ€™re building. There are a lot of other words for thatโ€”user pull, signalโ€”but your mantra of gravity really resonates with me now.โ€ 


Microsoft employees have already been using an early Microsoft Scout desktop experience. We built this to learn how always-on agents show up in real work, and weโ€™re seeing it take on coordination, surface risks earlier, and keep work moving without constant prompting. 

Weโ€™re now extending that early experience to Frontier organizations. Microsoft Scout is available as an experimental release through Frontier, giving customers a chance to explore how it can fit into their own workflows. 

Access requires Frontier enrollment, Intune policy configuration, and an opt-in attestation. Users with a GitHub Copilot license can then download and install the experience. Learn more.

How Excel got agentic: An interview with Microsoft Director of Science Mukul Singh

When Mukul Singh made the jump from pure research into product, it was a leap of faith. But he had an idea that he wanted to bring to life: delivering agentic AI capabilities in Excel. 

While this was well before buzzwords like โ€œthe agentic AI eraโ€ had cultural cachet, the research was already headed in that direction. So armed with a prototype and a healthy dose of ambition, Singh made his pitch. 

Two years on, heโ€™s fully transitioned from his role in Microsoft Research to a new gig in the Office Product Group and successfully delivered the ability to edit with Copilot in Excel (previously known as Excel Agent Mode). Not ones to rest on their laurels, the team quickly went on to ship agentic capabilities in PowerPoint, Word, and Outlook. Itโ€™s changing the way people get work doneโ€”and it started with the hypothesis that Excel, at its heart, is a low-resource programming language. 

We sat down with Singh to learn more about his journey from research to product, the science and research behind Officeโ€™s new agentic capabilities, and why Excel was the perfect testbed for agentic AI. 

CL Command Line

To kick us off, tell us a little about yourself.

MS Mukul Singh

Iโ€™m a researcher in the Office Product Group team. I recently started a science team focusing on agents and AI for the Microsoft Office product portfolio. I was originally in Microsoft Research, working on research full-time, publishing papers, and very far away from the product world. To be honest, itโ€™s been an incredible journey getting to go from research to then being embedded in the product space.

CL Command Line

How long ago did you make that transition?

MS Mukul Singh

It was only two years agoโ€”and right at the cusp of when the Excel Agent Mode work started. In fact, that was the catalyst. I had no intention of ever moving out of academia and deep research. And, you know, Microsoft Research is one of the best labs in the industry thatโ€™s still connected to academia. So I was pretty okay with my life. I didnโ€™t want anything else. It was the most perfect blend that I could hope for.

And then this project in Excel started, and there were some initial discussions. I thought it sounded interesting, because one of the things in research that you always feel is missing as a gap is that you donโ€™t see your work actually delivering value. You see it deliver a lot of theoretic valueโ€”you see its shape and the direction of the world, per se. Other people might take your research direction and extend it in meaningful ways. Research does shape society in a way, but you donโ€™t see any immediately measurable impact.

So at that point, I felt like I wanted to work on something where I could see that happenโ€”where I could watch the impact unfold in front of me.

CL Command Line

What are some of the research questions that ultimately led to Excel Agent Mode (which weโ€™re now calling edit with Copilot in Excel)?

MS Mukul Singh

My research in MSR and all of my papers previously had all been about AI for low-resource programming languages. I like to explain low-resource coding languages as languages that are very obscure and make up less than like 0.1% of the entire coding community. So AI models are generally bad at them because they just learn off the internet and known sources.

To give you an example, internally a Microsoft thereโ€™s a language called Kusto Query Language (KQL). Thatโ€™s just used for telemetric querying. Now, itโ€™s a public languageโ€”itโ€™s published. But no one outside of Microsoft uses it because why would they? We designed it for our database systems. So that’s the type of languages that the models are bad at.

All of my research was looking at how we could make models good at these languages, which they are not naturally good at. We need to drop in hints, cues, documentation, give it retry mechanisms and everything.

When I was initially approached about this work in Excel, I was at first very skeptical of how that and my work might be related. Iโ€™ve done a lot of tabular research, sure, but itโ€™s not Excel. But then they drew the parallel that, actually, Excel is just another low-resource language programming. It has its own internal language. It has its own engine. Itโ€™s just that the model doesnโ€™t know it.

Excel is just another low-resource language programming. It has its own internal language. It has its own engine. Itโ€™s just that the model doesnโ€™t know it.
– Mukul Singh
CL Command Line

Yeah, in your LinkedIn post, you talked a little bit about how Excel functions like a low-resource programming language. What really surprised you about the project when you dug in?

MS Mukul Singh

So the vision originally for Excel Agent Modeโ€”and, by the way, kudos to the team and their thinking. This was before any agents. Today, everything is agents, right? You can automate, you go to an app and assume that thereโ€™s a button somewhere that will do it for you. But that didn’t use to be the case. Excel, I just didnโ€™t think of it as an AI-forward app. I thought of Excel as an app that adapts, right? That doesnโ€™t need AI. But the vision at that point was that the team wanted to automate end-to-end user workflows.

If I open Excel, anything I have in mind that I want to do, this agent Iโ€™m building should be able to do it. That was a very difficult vision to achieve. In fact, thatโ€™s the reason that this project took so long and had so many setbacksโ€”because we set our ambition up so high, before the models even had the capability to be good enough to do anything like this at scale.

Say you want to add a pivot table, right? Thatโ€™s a common task. I donโ€™t know how to do it, but I know people do it. Itโ€™s just like a five- to 10-line code snippet that, wherever someone clicks the button, โ€œCreate pivot table,โ€ internally that code is run. Now, we could connect the model and it could generate all of that code, which is just some random JSON and JavaScript objects. To us, itโ€™s like gibberish text, but itโ€™s completely deterministic and exactly controls the behavior. And the good thing about Excel is that all of its surface is programmable.

This is not true for all apps, by the way. Very few of Microsoftโ€™s apps are truly programmable, but Excelโ€”you have to hand it to the engineers 40 years ago when they were setting it up: They made sure that everything is programmable end-to-end.

CL Command Line

What are some of the twists and turns that the work has taken over the last two years?

MS Mukul Singh

When we started this project, the vision really hit home. We had insane videos that the product managers and designers made, showing how the product is today. But this was two years ago, right? And the videos were the same.

So you see the disconnect was that everyone, leadership bought in. Like, this is the future. We want to invest in this. Itโ€™s the right thing to do. And we got a very strong crew of people. I was brought in. We were all working on it, but the reality was that the models werenโ€™t good enough. This was before the age of the racing models. The best model we had to work with was 4.0, and anyone who has played with models knows that 4.0 just cannot do long chain tool calling.

It used to collapse after a couple of calls, and it was only able to do things like start a formula, start a problem, which at that time was still cool andโ€”bless our marketing team, they were able to make that such a good feature with the help of design and everything. But even that, to us, felt like, โ€œOh, weโ€™re falling short.โ€ And they were like, โ€œNo, this is still great.โ€

The industry just wasnโ€™t here yet. That was, I feel, the weakest moment of the project where there was this doubt. Like, is this just too aspirational? Is it just not possible? Did we predict the future wrong, or will the models not even get there for like 20 years? We just didnโ€™t know.

We had promised a lot to customers on the backing of these researchersโ€™ point of view, and now we were in a space where we didnโ€™t feel confident that we could deliver. There were debates about whether we should just cut this project and rebrand it into something completely different.

So it was indeed quite the journey. We were shooting way above our weight class with very little evidence other than just the intuition of maybe three people who said, “We think this is where the world will end up.โ€

CL Command Line

When did you get a sense that the models were headed in the right direction in terms of reasoning and long chain tool calling?

MS Mukul Singh

I think thatโ€™s a very good question. When OpenAI announced their first series of reasoning models, that was a pivotal moment for us. We tried the model, and it couldnโ€™t solve any of the promised scenarios we had. But the traces showed signs of life. Like in the pivot table example: It tried to generate the pivot table code. It ran itโ€”it just gave back an error that the area where youโ€™re trying to create the pivot table already has data in it.

Now, the previous models at this point would either keep looping in this same error, just give up, or do some other random gibberish text response and not recover. But o1 tried to recover. That was the first sign of life that, OK, this is now working in a chain. It does something, looks at feedback, and tries to recover and keep trying until it succeeds.

It went up to like 20, 30 tool calls, still not able to solve real complex tasks. But we thought that if we reinforced it with the right information, it might be able to do something.

CL Command Line

This is backtracking a little bit, but when you ran up against the limitations of the modelsโ€”when it seemed like maybe you were headed down the wrong path and the research had it wrongโ€”what kept you going?

MS Mukul Singh

Iโ€™ve been in the space of generating low-resource programming languages for a while. I had even published papers for Excel in general, so I know the ecosystem. Everythingโ€™s built on top of Excel. So based on all of the research, we had a very strong intuition that this is where the models were headed. And our parallel was very simple: that coding agents, like people using GitHub Copilot and VS Code, and Excel should intuitively be no different.

Their implementation and all the UX decisions are different, but they are the same in principleโ€”it’s a surface in which I do manual work. I want that automated, and Iโ€™m doing that through code. Our parallel was always that Excel is an IDE. People donโ€™t see it as an IDE. They see it as an app, but thatโ€™s just because itโ€™s presented as an app. Itโ€™s really just an IDE. For analysts, itโ€™s the equivalent of VS Code to a developer.

CL Command Line

Youโ€™ve been talking about this, but Iโ€™m going to ask the question directly: What is it that makes Excel a really solid testbed for agentic AI?

MS Mukul Singh

I truly believe that Excel is the first large-scale enterprise app that was actually automated by an agentโ€”meaning that the agent can take meaningful action in the app. So it doesnโ€™t have fixed workflows. Itโ€™s actually controlling it. And what makes Excel the perfect testbed is that itโ€™s programmable. All of it can be controlled by the agent.

Itโ€™s not just code, because that code has real consequences in the app that you can see. If I add a chart, I see a chart there, right? If I connect a formula to a different sheet, I see live updates. So itโ€™s kind of a living environment. Itโ€™s a live environment in which Iโ€™m making changes. And if I make changes, the environment will undergo some change. And Iโ€™ll use that as feedback, so thereโ€™s observability. And that is the best testbed.

An agent needs an action space that allows you to interact with an environment. And it needs feedback from the environment. Now, this seems trivial, but honestly, very few apps fit this charter perfectly. So this loop made Excel very interesting. All of the research across everything weโ€™ve discussed, it’s been over a span of 17 or 18 research papers all going back two to three years. When someone looks at it at first, they might not even connect the dots. But thereโ€™s like three papers on just the best representation of data for Excel sheets. And people will think, “Oh, thatโ€™s probably for storage and optimization and context querying. But no, itโ€™s just that we need a concise representation for the model.

Excel actually showed the way for a lot of the apps in the industry in general that this is how an automation pattern works. At least within Microsoft: After Excel, PowerPoint followed. Then Word followed, the same pattern. And Outlook was recently announcedโ€”same pattern, same research crew delivering all of that, one after the other, just because all of the fundamentals are there.

Excel is the first large-scale enterprise app that was actually automated by an agent.
– Mukul Singh
CL Command Line

So your team was involved in expanding the editing with Copilot functionality across the Microsoft Office product suite?

MS Mukul Singh

Yeah. After my stint at Excel, I kind of figured out that, you know what? This is kind of fun. In fact, itโ€™s very similar to research where you get a vague abstract problem, you have no guidance, and you just try to go solve it. Talk to people. Figure things out. Itโ€™s like the same environment, just the difference is that when it actually ships, you feel a sense of accomplishment, and you can point people to it. Like I can tell an Excel guru, โ€œOpen that side panel. Try a query.โ€ Youโ€™ll be amazed, and I built that.

So the moment that Excel was in a stable state, we handed it off back to the feature teamโ€”the PMs and designersโ€”to run with it. And then we moved on to the next surface, PowerPoint, and that seemed even more interesting. Ever since I moved into a Director of Science role inside the Office Product Group, where Iโ€™m overseeing all of the agent work, Iโ€™ve realized that itโ€™s all based on very similar patterns. And it just so happens that all of my research aligned very closely with where the industry headed because, let’s be honest: Eight years ago, when I was starting my research for low-resource programming languages, at that time, there were just embedding models. At the time, it just seemed interesting. We had no idea the shape that agents would take.

Going into this field, the models were already good at good languages, so what could I contribute there? The only place where I could meaningfully contribute was with the things the models were bad at. So I literally made a list of everything these models struggled with, and it just stood out that programing seemed useful. If it can write good code, someone somewhere will be happy.

CL Command Line

Were there any hiccups along the way? Did you run into any unexpected technical challenges?

MS Mukul Singh

At first, we ran into the faster horses trap. Weโ€™d show customers these videos and ask, โ€œAs an analyst, will you be more productive with this tool?โ€ And everyone said, โ€œIt needs to come back with an answer in 30 or 40 seconds. Thatโ€™s how long I can wait. Thereโ€™s no way in the world that Iโ€™m going to sit there for 10 minutes and leave it running. No one works like that. Iโ€™d cancel that operation after 30 seconds.โ€

Out of every customer we talked to, not a single person had ever said that they were willing to go beyond one minute of wait time.

CL Command Line

Right.

MS Mukul Singh

So we were optimizing for that. It needs to complete faster. If the model is making three errors and recovering, thatโ€™s not good enough. It shouldnโ€™t make those three errors. And that sent us down paths of optimization that are very tricky. Like today, theyโ€™re still not solvedโ€”theyโ€™re that difficult. But we thought that was non-negotiable for the product.

Then this company called Shortcut came out, and their app ran for 25 minutes on a single query. But the results were amazing. Initially people said, โ€œWhoโ€™s going to wait 25 minutes?โ€ But within a week, everyone said, โ€œI now just log in, push the query, and just leave. I donโ€™t need to do like anything.โ€

And we were like, what? But for every one of our customers that we talked to, their mindset immediately changed. They were asking for faster horses, but then someone delivered them a car. And now they understand that thatโ€™s exactly what they needed.

They were asking for faster horses, but then someone delivered them a car.
– Mukul Singh
CL Command Line

Thatโ€™s really interesting.

MS Mukul Singh

The challenges were really around customer expectations. We went with the assumption that all our apps are IDEs. But the hypothesis starts to break down because people use these apps with nuance. And the moment we fail to understand that, it goes from a good to a bad experience. For Excel, it was that people are willing to wait for long-running tasks. But they need auditability. It canโ€™t just work behind the scenesโ€”it has to show its work. It needs to be computed on the sheet.

Similarly, for PowerPoint, people really care about their brands and templates. Initially the version of the PowerPoint agent that we shipped, which if you asked me to rank them, I would say itโ€™s the best version that we builtโ€”that was the one that everyone hated. We had optimized for a PowerPoint agent that works with its own independence, like in a vacuumโ€”because thatโ€™s the way I use PowerPoint. I start from scratch, no templates. I just have some information that I need to present, and I want to find the best way to do that. But there were other very real constraints that we had to understand. So PowerPoint really pivoted to take into account templates and brand guidelines.

Similarly for Outlook, we found that people really care about confirmation. Like with Visual Studio and all these IDEs, they try to optimize for the least user engagement required, because thatโ€™s automation, right? You can leave it running and you donโ€™t have to worry about it unless thereโ€™s something that you really need to look at. So they really try to cut down on the model asking something back.

But in Outlook, the story is completely the reverse. People actually love it when the model gives them a list of things that it proposes, and you can just accept or delete each of them in a list. So like:

  • Send this draft email to this person? Accept.
  • Create this to-do list? Accept.
  • Delete these seven emails? Reject.

And, again, it was an anti-pattern.

CL Command Line

What can you tell us about the tech transfer process and how your research made its way into the product?

MS Mukul Singh

Yeah, that was actually tricky. I feel like, in general, a lot of people struggle with taking their research and landing it in a product. Thereโ€™s a very weird gap, because the product teams are very direct about needing to talk to more researchers, and the research teams are keen to get the product groupโ€™s attention because everyone wants their work to be used and get funded. But thereโ€™s still this weird gapโ€”itโ€™s just not well connected. And the surprising thing is, itโ€™s not because of a lack of will from either side.

Itโ€™s because product always comes with so much nuance. The product teams canโ€™t just blindly trust that the research teams are going to understand everything and build it. And for the research team, itโ€™s very hard to put themselves in the product teamโ€™s shoes and understand all the constraints. Maybe it needs to run in 10 seconds or less, or it needs to have auditability traces. Thatโ€™s something that the research teams would feel is a very strange objective.

But at least for Excel, I think the process was smoother because we operated as an integrated team.

CL Command Line

What was the overall team dynamic like?

MS Mukul Singh

For Excel Agent Mode, it was a crew of just 10 or 11 people. Everyone had a title, but the titles meant nothing, right? There were PMs checking in PRs. There were devs writing papers. And there were researchers writing specs. There was just everyone on board working as if it were a startupโ€”logged into a conference room and just checking in change after change. That was honestly the most fun time, when it was just people building stuff, coming up with ideas. But then we did do a proper handoff.

Taking the research into the project became easier because everyone discussed everything openly, so everyone understood the same things.

CL Command Line

What avenues for future research did this work open up?

MS Mukul Singh

I think a lot. Before this, I donโ€™t think people were really thinking of agents for things that normal people use as apps. That just wasnโ€™t a concept. And Excel has already given way to PowerPoint, Word, and Outlookโ€” which are all entirely different surfaces, all just automating the app completely. There was significant uptake, even outside Microsoft, when people saw that, not only is it possible, but people love it.

This project was a testbed that showed two very distinct things: that it was possible to automate an app through these models, which previously was not the accepted truth, and that there was a lot of appetite for it.

Excel in its early days had a lot of flaws in the agent. But people overlooked a lot of that just because of those scattered moments of brilliance where they were like, โ€œOh my god, it did something that I couldnโ€™t even have imagined.โ€

This has opened the door so that, I think over the next couple of years, all of these apps that we use day to day will have an agentโ€”not to replace it, but that will be our go-to whenever we struggle to get something done. It showed the path, that this is possible for other apps, regardless of their complex surfaces.