
What happens when AI agents can rewrite millions of lines of code orders of magnitude faster than humans can review them?
At Microsoft, we’re working on exactly that problem.
We’re building and running AI agents that transform some of the world’s largest codebases, including Windows and Azure. Our work ranges from migrating a 400-million-line codebase to a new compiler toolchain to modernizing legacy C and C++ code into Rust—increasingly backed by formal verification.
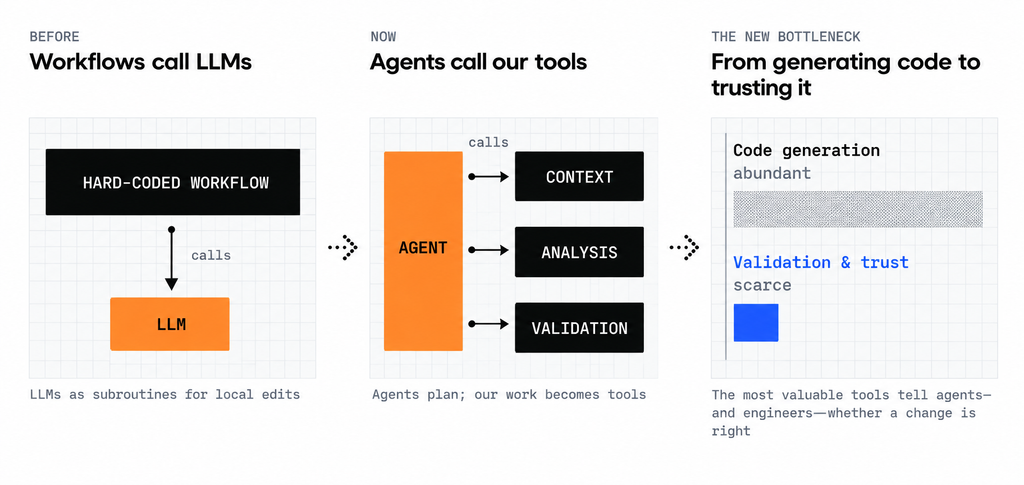
Generating code is becoming the easy part. Knowing whether to trust it is the real challenge. When agents make changes across hundreds of millions of lines of code, how do we know they haven’t broken something subtle? How do we preserve behavior, security, and architectural intent? And how can a small team of engineers confidently stand behind changes that AI agents make at that scale?
Since 2024, we’ve been combining AI agents with static analysis, testing, and formal verification to make large-scale software transformation practical and trustworthy.
These questions are at the heart of our work. Since 2024, we’ve been combining AI agents with static analysis, testing, and formal verification to make large-scale software transformation practical and trustworthy.
Along the way, the flow of control inverted. We began by hard-coding workflows that called LLMs as subroutines; by May 2025, agents had become better planners than our pipelines, and our job became building the tools that agents call. The most valuable of those tools are the ones that tell an agent—and the engineers behind it—whether a change is right.
We’re now continuously updating our approach through our flexible harness to leverage formal methods, decompose large-scale goals across complex systems, and tackle the kinds of problems that mature companies with large, complex codebases face. We’re also rethinking how humans and agents work together. Even as models and agent harnesses improve, the cognitive load on human experts is growing. Human attention has become the scarcest resource in agentic software engineering, and we design our tools to spend it where it matters most.
Human attention has become the scarcest resource in agentic software engineering, and we design our tools to spend it where it matters most.
This is the first post in a series about what we’re building, what we’ve learned, and the questions we’re still trying to answer. Here, we introduce some of the problems we’re working on and the ideas that connect them.
Migration
Imagine needing to make similar kinds of changes across hundreds of millions of lines of code, maintained by thousands of engineers. That’s the challenge of large-scale code migration. Generating any single edit is easy. The hard part is getting thousands of edits right in the same way: capturing what experts know, validating that knowledge, and applying it consistently—without pulling every engineer in the organization into the effort.
We define migration as a transformation applied across a codebase to achieve a specific engineering objective, such as upgrading dependencies, adopting a new compiler, remediating static-analysis findings, or moving to a new platform. Our case studies include migrating the entire Windows codebase—which is several hundred million lines of code—to add support for the Clang/LLVM toolchain; remediating findings from CodeQL, PREfast, and Roslyn analyzers across codebases; and retargeting services from x86 to ARM.
We make a deliberate choice about the operating model: a very small team of migration experts can—and should—drive a large migration. Instead of distributing migration ownership across the broader engineering organization, we concentrate expertise and amplify it with agents.
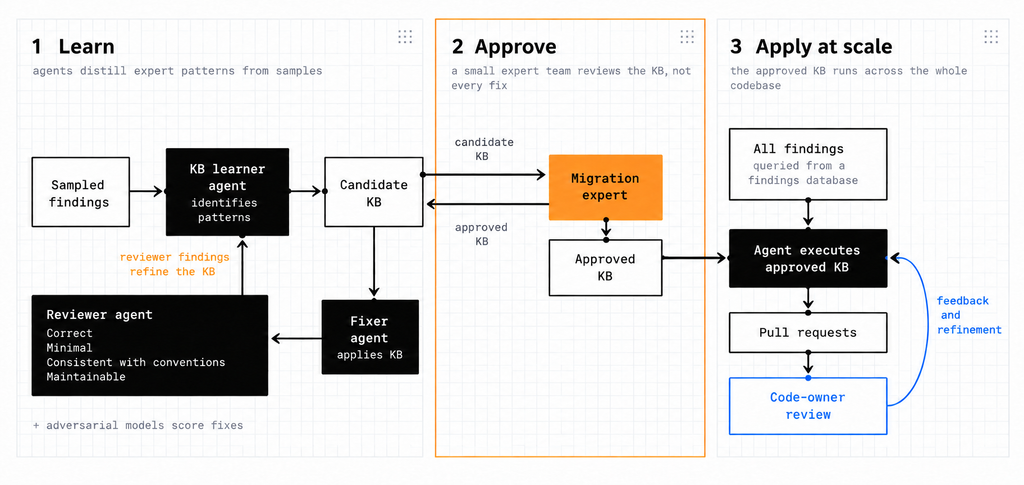
Agents first learn a candidate knowledge base from sampled findings. A reviewer agent scores each proposed fix for correctness, minimality, consistency with file conventions, and maintainability, and its findings refine the knowledge base. Experts then approve the knowledge base rather than individual fixes, and agents apply it across the codebase. Human feedback remains essential, but we direct it where it has the highest leverage: approving knowledge and resolving novel or ambiguous cases. Grouping similar fixes for review further reduces the cognitive load on reviewers.
Language modernization
Much of the world’s most critical software is written in languages like C /C++ that make memory-safety bugs easy to introduce and hard to eliminate. Rewriting in Rust promises safety by construction—but only if the rewrite preserves exactly what the original code did. At the scale of real systems, a manual rewrite is rarely practical, and an automated one is only useful if we can trust it.
Our work focuses on moving legacy codebases to Rust, and the rapid improvement of models and agents has changed what is possible:
| 1 | January 2025 Generated Rust code that didn’t compile. |
| 2 | June 2025 Code compiled but didn’t run correctly or pass tests. |
| 3 | September 2025 Working translations of approximately 30,000 lines, with manual guidance. |
| 4 | February 2026 onward Modernizing large codebases with significant automation. |
Each step moved the bottleneck—from compiling to passing tests to validated behavior at scale. As generation improved, the challenge became deciding what to modernize and showing that the result is right.
We’ve built interactive experiences that help engineers visualize the module structure and layering of a codebase and decide which components to modernize, and in what order. Our tools then produce both the modernized code and its validation strategy.
We’ve found that migrating feature by feature works better than translating a component line by line. A feature is a unit of user-visible behavior that we can validate end to end with scenario-driven tests, and each feature gets its own validation gate. Differential testing compares source and target behavior, and tests held out from the agent—so it can’t overfit to them—measure the robustness of the translation. Most recently, we’ve begun extracting formal specifications from the source, carrying them into the target language, and using Verus to prove that the modernized code satisfies them.
Specification-driven development
Agents can produce changes faster than people can assess them, and locally plausible code can still violate architectural assumptions, distributed protocols, security boundaries, or operational invariants. Tests catch some of these problems, reviewers catch others, but neither keeps pace with the rate at which agents produce changes. We believe the answer is to make intent explicit. As agents write more of our code, developers’ attention is shifting from writing code to managing the specifications that guide agents and validate their output. We’re building tools that put formal, interpretable specifications at the center of the software development life cycle.
Our first step is to infer formal specifications (e.g., TLA+) from existing codebases using agents. These specifications capture concurrency, fault tolerance, and other aspects of critical software components. We use tools like TLC to check that execution traces of the implementation are admitted by the specifications. This gives us evidence that the specifications admit the implementation’s observed behavior; whether they also capture what the system is supposed to do is a harder question—and one we return to below. When a trace is not admitted, the discrepancy may point to an implementation defect, an inaccurate specification, or an invalid test, and agents revise whichever is wrong.
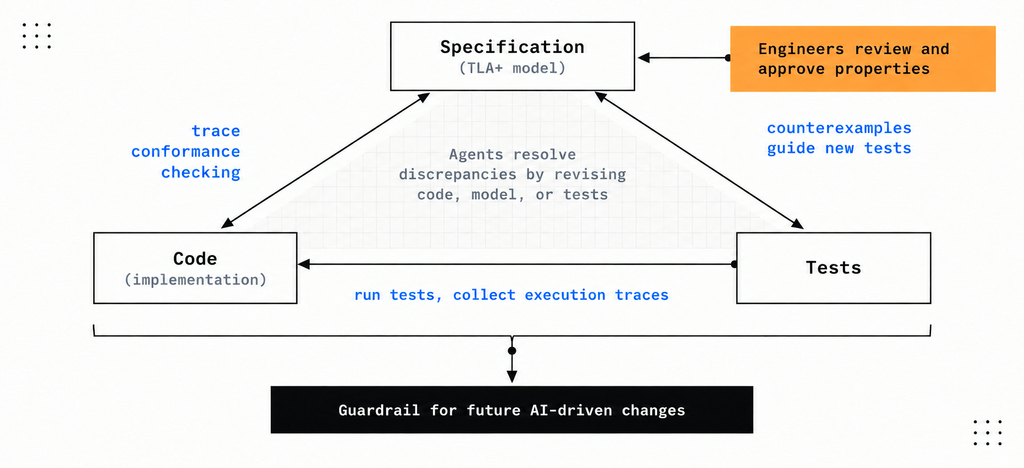
Once we have specifications, we put them to work. They’re a good source of rainy-day test cases that exercise tricky concurrent interleavings and fault scenarios. We model check candidate properties and inductive invariants on small, finite configurations to find counterexamples quickly, and we prove properties for all configurations in F* and Lean, using a TLA+-to-F* and TLA+-to-Lean compiler that we’re building. For brownfield codebases, this layer of specifications, test cases, and properties becomes a guardrail for future AI-driven changes.
Our goal is to bring the power of formal methods to every engineer without requiring them to become experts in TLA+ or formal verification. The engineer reviews and approves the properties the system must satisfy; the agents find the inductive invariants needed to prove them. As specifications become comprehensive, they can also anchor modernization—which is how we’re approaching the translation of C/C++ into Verus-verified Rust.
Open questions
Here are some open questions we’re grappling with:
- Can we trust specifications written by AI? When an agent infers a specification from the very code it is meant to check, how do we know the specification captures what the system should do rather than simply what it currently does?
- Can we verify more than functional correctness? Can agents help us reason about security, performance, and reliability, beyond simply checking whether code produces the expected output?
- Will engineers eventually stop reading code? If agents generate code and verification tools prove that it satisfies approved specifications, can engineers stop reading code and work only at the level of specifications?
- Who owns code when every agent can change everything? Traditional code ownership assumes engineers work within relatively well-defined boundaries. Agentic development challenges that assumption. What replaces it?
These aren’t hypothetical questions for us. They’re shaping what we build next.
We would love to hear what you see in your own work, where you disagree with us, and which problems you think matter most. Please feel free to reach out with your thoughts.